Orbit · Games · Data science · September 2025
Four in a row against five networks
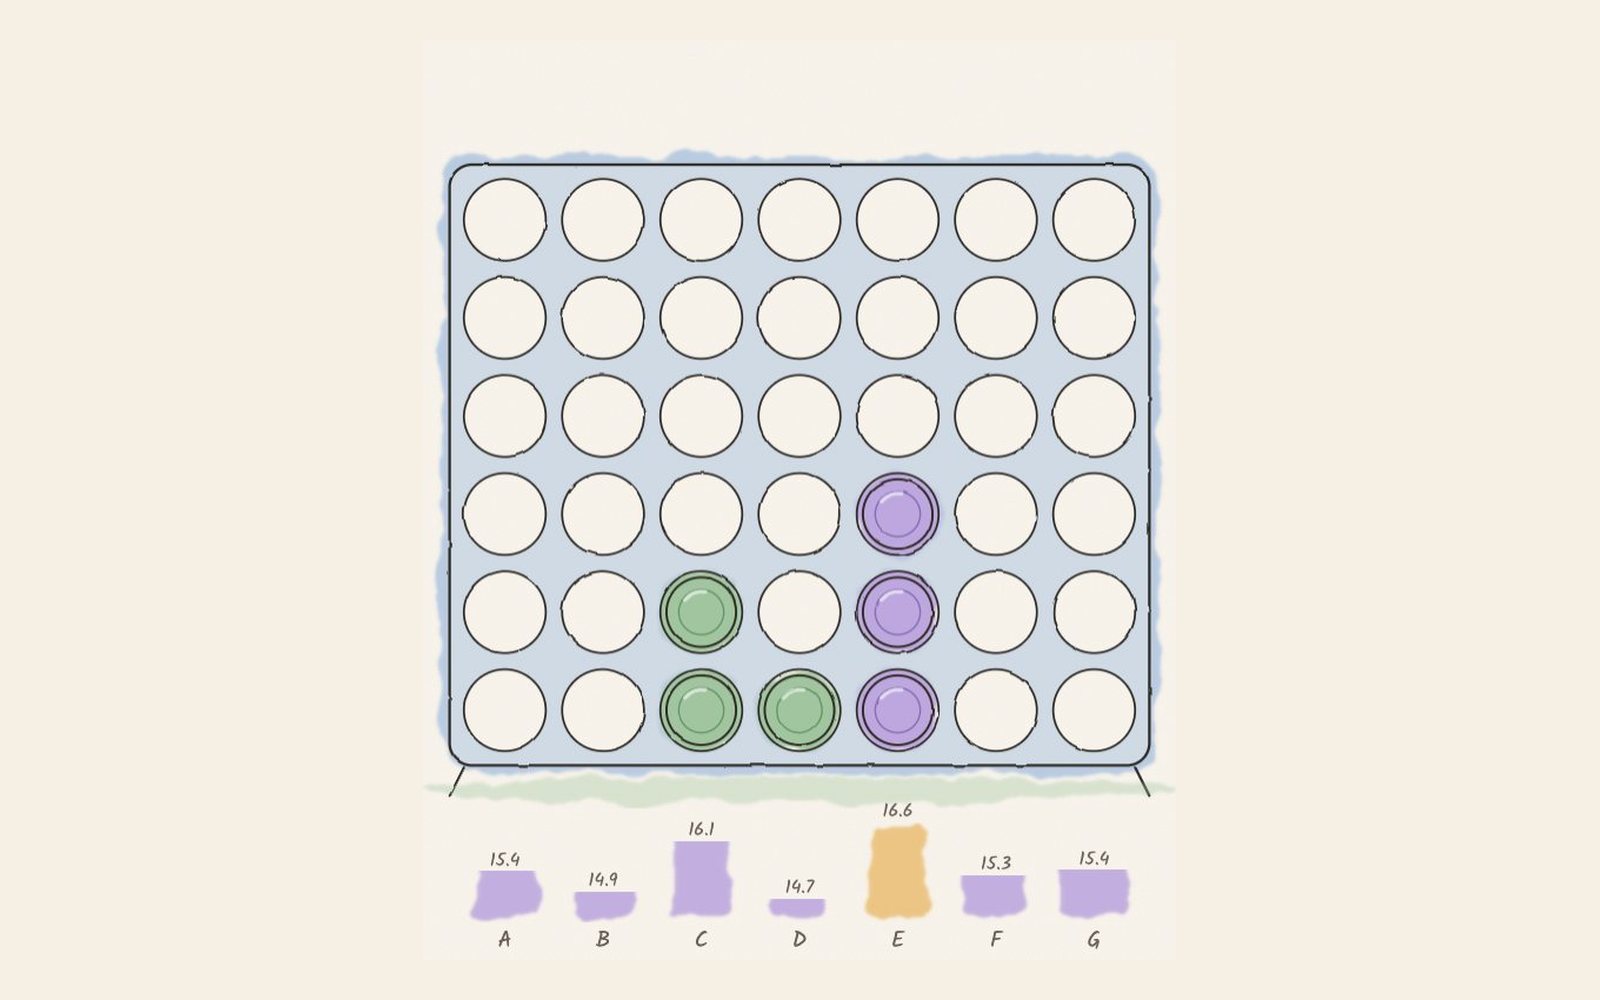
Connect 4 ensemble. Deep reinforcement learning agents trained on hundreds of thousands of games. An ensemble of the best five won a tournament against 35 other AIs, and you can play it here.
Connect 4 is small enough to learn and big enough that nothing can memorise it: about 4.5 trillion positions. That makes it a perfect sandbox to see what reinforcement learning really needs.
I started with two simple opponents to set the bar: one that plays at random and one that follows a few hand-written rules. The rules player beats random 99% of the time, so any learning agent first has to beat it.
The agents are Dueling Double DQNs. The first versions looked at the board as a flat list of 42 cells. The later ones are convolutional networks, which see lines and diagonals much as a person does.
The hardest problem was forgetting. An agent that learns to beat one opponent often loses what it knew against the previous one. Curriculum learning, a reservoir of old games to replay and slowly updated target networks kept the knowledge in place. The strongest model trained on 750,000 games.
The lesson I took away is that an agent only gets as good as its sparring partners.
In the end no single network won. I took the five best checkpoints and let them vote: each scores every column, the scores are averaged with fixed weights, and the best legal move is played. That ensemble beat 35 other AIs in a tournament.
The five networks now run directly in this page, so you can try your luck.
Play the ensembleThe essayCode ↗
Made with PyTorch, Dueling Double DQN, CNNs, curriculum learning, JavaScript.
Comments
Sign in with GitHub to leave a comment or react.